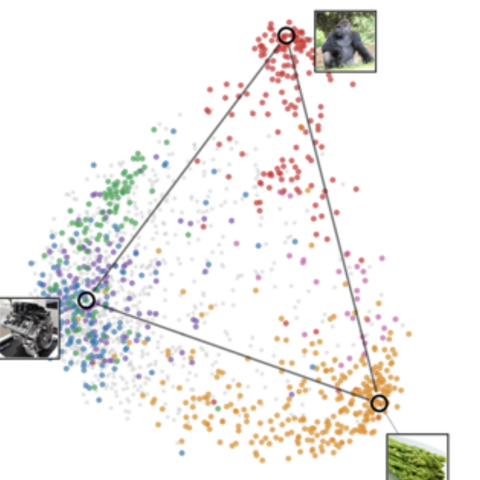
How fine-grained does a learning signal need to be for a neural network to see like a human? We trained hundreds of convolutional and transformer networks on tasks that distinguish only a handful of broad, data-driven categories and compared them with macaque electrophysiology, human fMRI, and human similarity judgments. Networks trained on as few as 8 categories match or exceed the neural alignment of 1,000-class models, and they align more closely with human perception than fine-grained, self-supervised, or large-scale vision models. Human-like vision can emerge from remarkably coarse feedback.
Brains learn to see from far less experience than deep networks, which need millions of labeled images. We asked whether a simple principle called efficient coding, where each layer just captures the main patterns of variation in natural images, could explain this. We built a deep network that learns this way, layer by layer, with no labels, tasks, or backpropagation. Its features look a lot like those in biological vision, from edges and colors up to textures and shapes, and they predict activity in human visual cortex. Adding a small amount of supervised training on top of this leads to faster learning and better brain alignment when data is scarce.
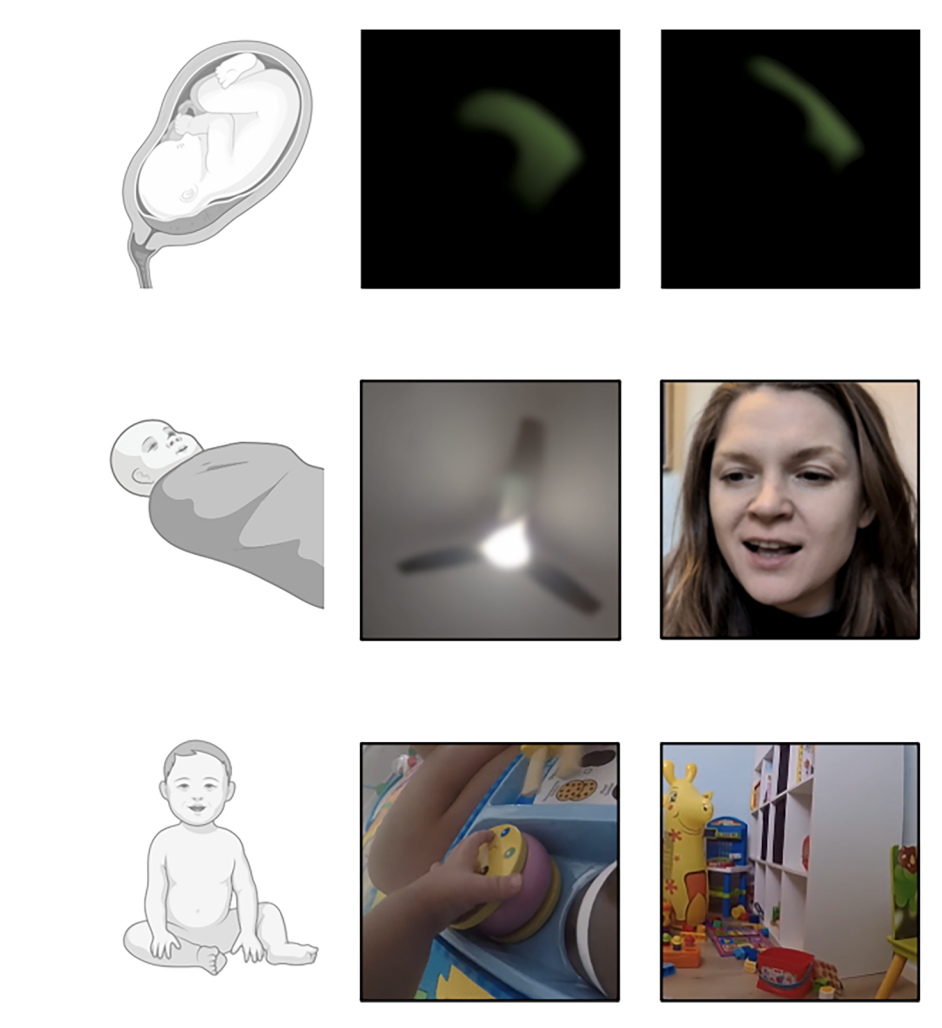
Most AI models of the brain try to match the adult brain, the end state of intelligence. In this review, we argue that we should also model how intelligence develops in the first place. Children learn quickly because their brains, experiences, and learning goals change in ways that are well suited to learning. We describe how these developmental principles could be built into AI systems. We also propose the abilities of young children as a natural set of benchmarks for evaluating AI models.
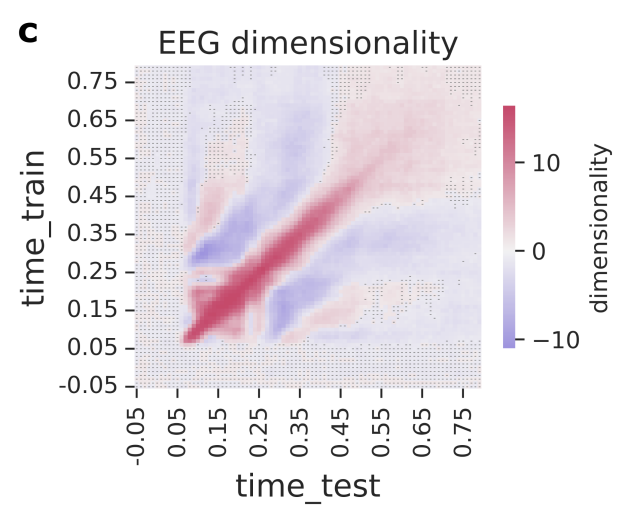
When we see an object, the brain's response unfolds over a few hundred milliseconds. We used large EEG and MEG datasets to track how the complexity, or dimensionality, of these responses changes over time. We found that dimensionality expands rapidly, peaking within about 100 milliseconds, and then slowly decays. The more dimensions there are, the more information about the object can be read out from the brain. Neither deep neural networks nor models built from human similarity judgments fully explain these responses, which means there is still a lot about dynamic brain activity left to understand.
We show that individual differences in visual experience emerge from high-dimensional neural activity patterns during naturalistic movie viewing, with distinct latent dimensions capturing behaviorally relevant aspects of perception. This multidimensional geometry, revealed through spectral decomposition, explains inter-individual variability beyond what conventional methods capture.
We examined whether visual neural networks align with brain representations due to shared constraints or universal features. Analysis of diverse networks revealed shared latent dimensions for image representation. Comparing these to human fMRI data showed brain-aligned representations are universal across networks. This suggests similarities between artificial and biological vision arise from core universal image representations learned convergently.
We find that untrained convolutional neural networks can produce brain-like visual representations. This challenges the view that extensive training is necessary for such similarities. The key factors are the networks' architecture, specifically how they compress spatial information and expand feature information. This suggests that the basic structure of convolutional networks mimics biological vision constraints, allowing for cortex-like representations even without learning from experience.
Is it possible to deeply understand neural representations through dimensionality reduction? Our recent work demonstrates that the visual representations in the human brain require interpretation within high-dimensional spaces. Moreover, we reveal that traditional methods like representational similarity analysis fail to detect this high-dimensional information in cortical activity; instead, a spectral approach is necessary. This research uncovers a vast expanse of uncharted dimensions that conventional techniques have overlooked but may be crucial for decoding the cortical code of human vision.
Investigating deep neural networks (DNNs) as models for the visual cortex, we found that higher-dimensional representations in these networks better predict cortical responses and improve learning of new stimuli, challenging the idea that lower dimensionality enhances performance. This indicates that high-dimensional geometries might be advantageous for DNN models of visual processing.